The lab
Part 4 (optional). The automated version
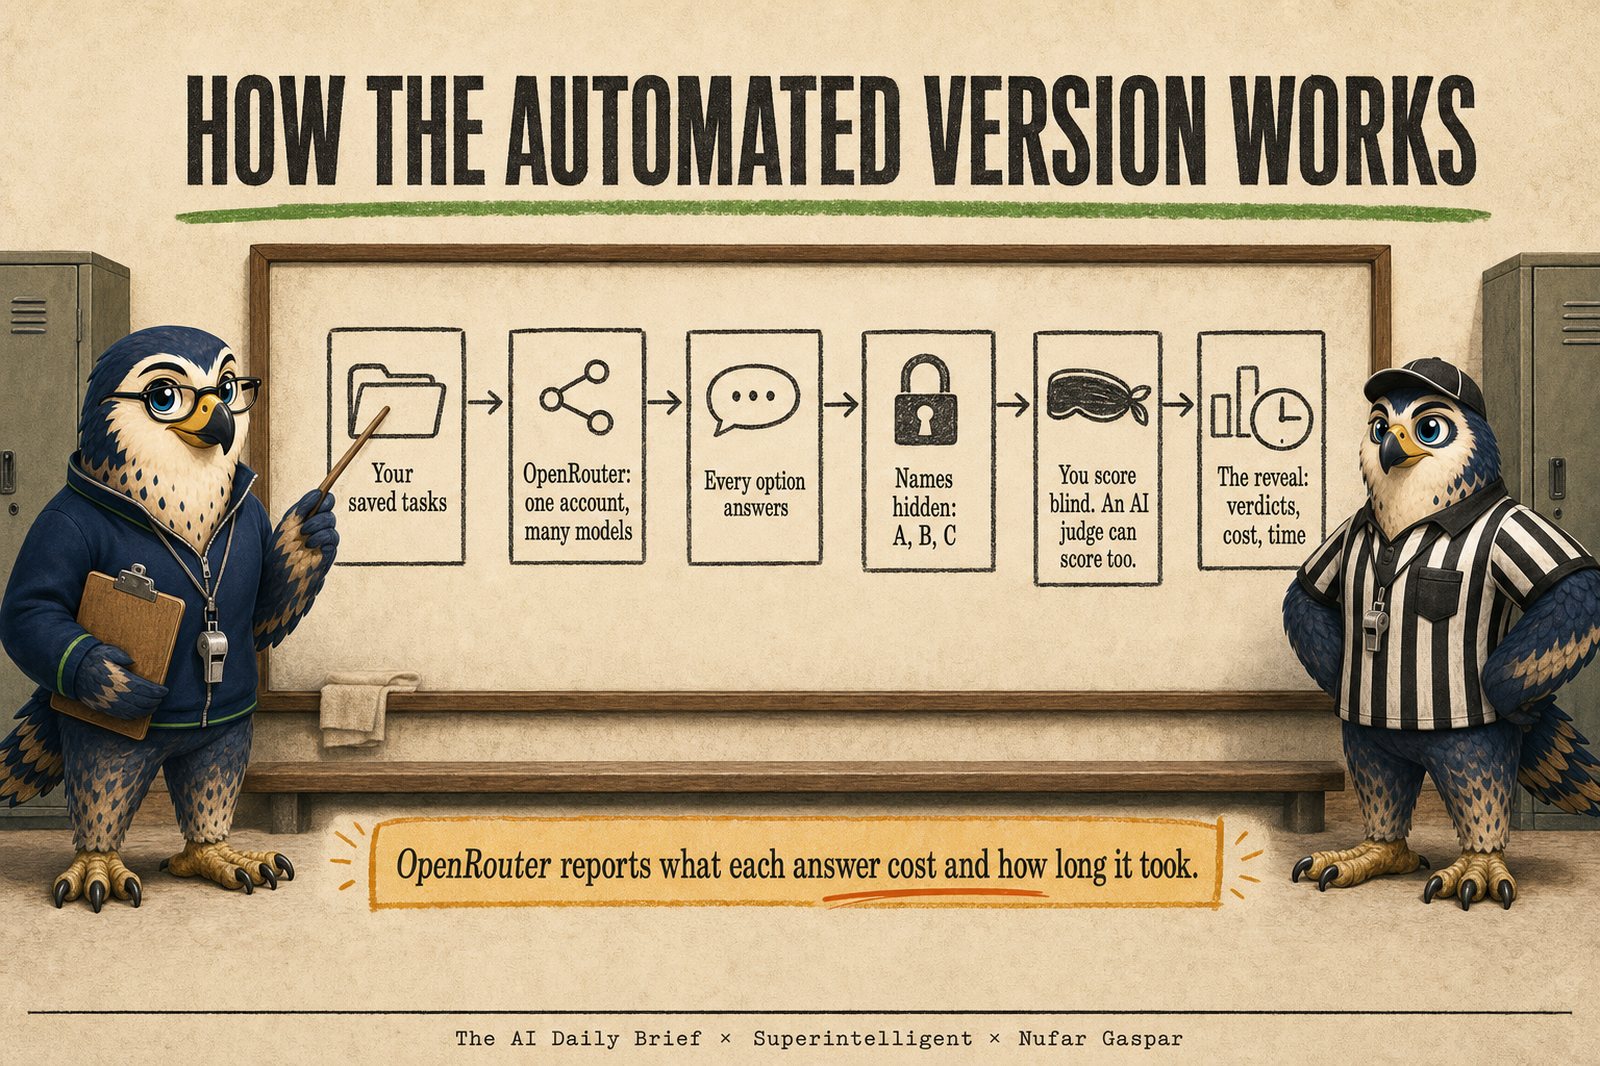
The Benchmark Runner is a small program that runs your personal AI benchmark for you. You give it your saved tasks and the names of two to four AI models. It sends every task to every model, hides which model wrote which answer, and opens a page in your browser where you read the answers and score them blind. Then it reveals the names and tells you what your own scores say: switch, split, or stay, with what each model cost and how long it took. An AI judge can score alongside you if you want a second opinion.
It is for people who are comfortable pasting an API key into a file and double-clicking a launcher. You do not need to write code. If that is not you, the taste test in the lab handout gets you the same answer by hand.
Get your key
A key (often called an API key) is a private code that lets a program use an AI model directly, billed to your own account. Treat it like a password.
The easy route: one key for many models. OpenRouter is one account that reaches models from most companies, and it reports what each answer cost and how long it took. Three steps:
- Create an account at openrouter.ai.
- Add a small amount of credit.
- Create a key, and paste it into the
key.envfile, as the START-HERE file in the download shows.
Other routes. Another model hub that offers the same kind of single key also works. So does a key directly from the company whose models you want to compare, such as OpenAI, Anthropic, Google, or xAI. A direct key works the same way, with one address changed in the settings file. Cost then shows as "n/a", and only time and length are reported. A direct key reaches one company's models, so comparing across companies in one run takes a hub.
What it costs. You pay the model companies for what you use, through your own account. The reveal page shows the exact amount for every run.
Keep it safe. Never paste a key into a chat, an email, or a shared document.
Run it
The download includes a START-HERE file with four steps: get a key, choose your options and tasks, run the tryout, and review blind, then reveal. Each step says what "done" looks like. The task files Prompt 1 saved in your my-ai-benchmark folder work as they are.
Choose two to four options. The program can run more than you can judge well. Reading seven answers to one request and holding them all in your head is hard work, and your judgment gets worse as the pile grows. At the next release, you add the new option to the settings file and run it again.
Score on the review page, then reveal
The review page opens in your browser. For each task it shows the request, your scoring guide, and every answer under a letter, in a different order for each task. Read every answer to a task before you score any. Then give each one a score from 1 to 5, with an optional note, and be stingy with top marks. Your scores save on every click, so you can stop and come back. An answer that is a web page is shown as a real page, with buttons to see it at phone width or open it full size.
When you are done, press one of the two buttons at the top:
- Reveal with the AI judge. The judge scores the same answers blind first, then you see the names.
- Reveal, my scores only. You see the names with no judge at all.
If you named the option you use today, the reveal shows a verdict card for each other option: Switch, Split, or Stay, decided by your own scores. Below the cards, it shows what each option cost and how long it took, for each option and for each task. Cost and time appear only after the reveal, because they are tie-breakers: they settle close calls once the answers are judged. "You and the judge" shows where you picked the same winner and where you differed. "The raw scores" lists every score, yours and the judge's, with the reasons.
The AI judge
The AI judge is a second reader, from a company that made none of your options. The first version gave top marks to almost everything, so it was rewritten as a tough editor. It ranks the answers first, gives at most one top mark per task, and treats competent work as a 3. It cannot see a web page. It reads only the page's code, so the look of a page is yours to judge. Where you and the judge differ, your own scores decide.
What stays by hand
Tasks that need web search or a build tool stay by hand, because the runner sends each request to the model as text. A task that asks for a web page can be answered as one file, and the review page shows it as a real page. Agent tools such as Claude Code or Cowork are compared by hand too. One tool cannot drive another, so you run each task inside each tool and save the answers into a folder for the blind-shuffle script.
OpenRouter's chat page can help with the by-hand route. It sends one request to several models at once and shows the answers side by side, with the names visible. It is a quick way to collect answers before you hide the names with one of the four ways in Step 3.
Let an agent tool set it up
An agent tool such as Claude Code, Codex, or Cursor can set the runner up with you, with Prompt 7.
Prompt 7: Set up the runner
Open your agent tool in a folder that holds your benchmark document, any made-up material your tasks use, and the benchmark-runner folder from the download. Paste this.
Help me set up the Benchmark Runner for my personal AI benchmark. In this folder you will find my benchmark document (my saved tasks, each with its exact request, its material, and its scoring guide, plus my decision rule), the made-up material the tasks use, and a benchmark-runner folder. The Benchmark Runner is a small program that sends each task to every AI option and saves the answers under random letters. It opens a review page in my browser where I score the answers with the names hidden. Then it reveals the names, with a verdict from my own scores and what each option cost and how long it took. An AI judge can score alongside me as a second opinion.

Before changing anything, read my benchmark document and the START-HERE and README files in the benchmark-runner folder. Where those files are more specific than this message, follow them.

Then interview me, one question at a time, and wait for each answer:

- Which options do I want to compare, and how is each one named on the service I am using? Keep it to two to four, because I will read every answer myself. If I name more, ask me which ones to drop.
- Is one of them what I use today? If so, I will get Switch, Split, or Stay for each other option. If not, I will get a lineup: my default, and which tasks go elsewhere.
- Do I want an AI judge as a second opinion? If so, it must come from a company that made none of the options. Refuse any judge that matches an option.
- Is my key already set up the way START-HERE describes? Remind me never to paste the key into this chat.
- Does any task need material you cannot find in this folder?

Then do the work. Convert each task into the format the runner expects, one file per task, keeping my request and scoring guide word for word. If a task needs web search or a build tool, tell me it stays by hand and leave it out. If a task asks for a web page, set it up to be answered as one file, so the review page can show it as a real page. Fill in the settings from my answers. Run one everyday task first and show me the lettered answers before running anything else, so I can check that the setup is fair. Once I approve, run everything. Then open the review page for me and explain how to use it: read every answer to a task before scoring any, score each answer from 1 to 5, and be stingy with top marks. My scores save on every click. I press a Reveal button myself when I am done.

After the reveal, save a copy of the reveal page and my decision next to my benchmark document. Then tell me in plain words: the total cost, the slowest task, the tasks where the judge and I disagreed, and any task where the answers differed so much in length that I should check the settings. Tell me how to rerun everything the next time something new comes out.
Done: the reveal page saved next to your benchmark document, and the steps to rerun it.
Platforms that do this for teams. Some products already run a side-by-side comparison with a scoring guide and an AI judge. LangSmith, Braintrust, and Langfuse each let you run your saved requests across several models, score the answers with an AI judge, and review them by hand. promptfoo does the same as a free, open-source tool for people comfortable with a command line. They are built for teams testing prompts inside software they ship. For one person comparing a few options on real tasks, they are more than you need, and none of them hides the names on options you choose. That is why the taste test and the small script exist. If your company already uses one, it will run the scored version for you.